Short answer: on the thing coaching exists for, getting people to their goals, yes, and the evidence is better than most people expect. Randomised controlled trials, real control groups, replicated direction of effect.
We build an AI coach, so you should read this knowing that. What follows is the evidence as it stands, the favorable half and the scoping half, with every study named so you can check all of it.
The trials, named
The serious work comes from Nicky Terblanche and colleagues at Stellenbosch Business School, with Joanna Molyn, Erik de Haan and Victor Nilsson.
- Terblanche, Molyn, de Haan and Nilsson (2022), PLOS ONE, "Comparing artificial intelligence and human coaching goal attainment efficacy". Two longitudinal randomised controlled trials over ten months, chatbot coach against human coaches against controls.
- The same group (2022), International Journal of Evidence Based Coaching and Mentoring, "Coaching at Scale". A six-month randomised trial of Vici, a purpose-built goal-attainment chatbot, with a three-month follow-up.
- Later work extends the same line, including a study of a chatbot coach supporting first-time graduate employees, and 2024 research in Frontiers in Psychology on the working alliance formed with AI versus human coaches.
That is a young literature, and it is a real one: randomised, controlled, longitudinal, published. Anyone claiming there is no evidence for AI coaching has not looked. Anyone claiming much more than the next three sections is ahead of it.
The headline result: goal attainment moved, a lot
In the six-month trial, the chatbot group's goal attainment rose 55 percent against 24 percent for the control group pursuing the same kinds of goals on their own.
Reported group sizes were 75 in the chatbot condition and 94 in the control, with measurement at baseline, monthly through the six months, and again three months after the trial ended.
Two details make that result stronger than the bare numbers:
- The momentum held. Three months after participants stopped using the chatbot, they still reported continued progress on their goals.
- The dose mattered. The more frequently people interacted with the coach, the more their goal attainment rose. The mechanism behaved like a mechanism.
And the ten-month head-to-head trials point the same direction from a harder angle: on goal attainment, the chatbot coach performed comparably to human coaches by the end. Not better, and the researchers do not claim better. Matched, on the outcome coaching is bought for, at software cost and software availability.
That is the claim this category properly rests on, and it is worth stating without hedging: structured coaching conversations on a schedule, delivered by software, moved people toward their goals in randomised trials, roughly doubling the control group's improvement.
What the effect did not touch, and why that is the right shape
The same six-month trial measured resilience, psychological wellbeing and perceived stress. None moved significantly.
Read that carefully, because it is the most misread finding in the literature. The tool under test was a goal-attainment coach. It moved goal attainment and left general wellbeing where it found it: the effect stayed exactly where the tool was pointed. A drill that made holes and did not also mop the floor.
Two practical conclusions follow, and both are buying advice:
- Buy this category for goals. That is what the evidence supports, and it is the whole job. A stalled goal is a goal problem, not a wellbeing problem.
- Distrust wellbeing promises from goal tools. Any coaching product promising that you feel better in general is promising precisely what the closest available evidence failed to find. The honest ones sell what the trials found: structure, follow-through, and progress you can point at.
Odyssey sells goal accomplishment. That is a deliberate match to where the evidence is, not a coincidence.
What humans still do better
The working relationship. The 2024 Frontiers in Psychology work found participants formed a stronger working alliance with human coaches in a single session.
Working alliance is the field's term for the quality of the bond and the agreement on the work, and it is a real advantage, so it stays on the human side of the comparison without argument.
What makes the picture interesting is a related study using a Wizard of Oz design, where people who believed they were talking to an AI were actually talking to expert human coaches. Alliance came out moderately high in both conditions, with no significant difference, which suggests part of the gap is expectation rather than capability, and part is real.
Either way, the split is clean and useful: matched on the task, behind on the relationship. The task is what the category sells.
The most practical finding: what kind of system got tested
Vici was not a general chatbot with a coaching prompt. It was a purpose-built goal-attainment coach, designed against a published framework, doing one job.
That distinction is easy to skim past and it is the most actionable line in the research, because the market sells both kinds and prices them the same:
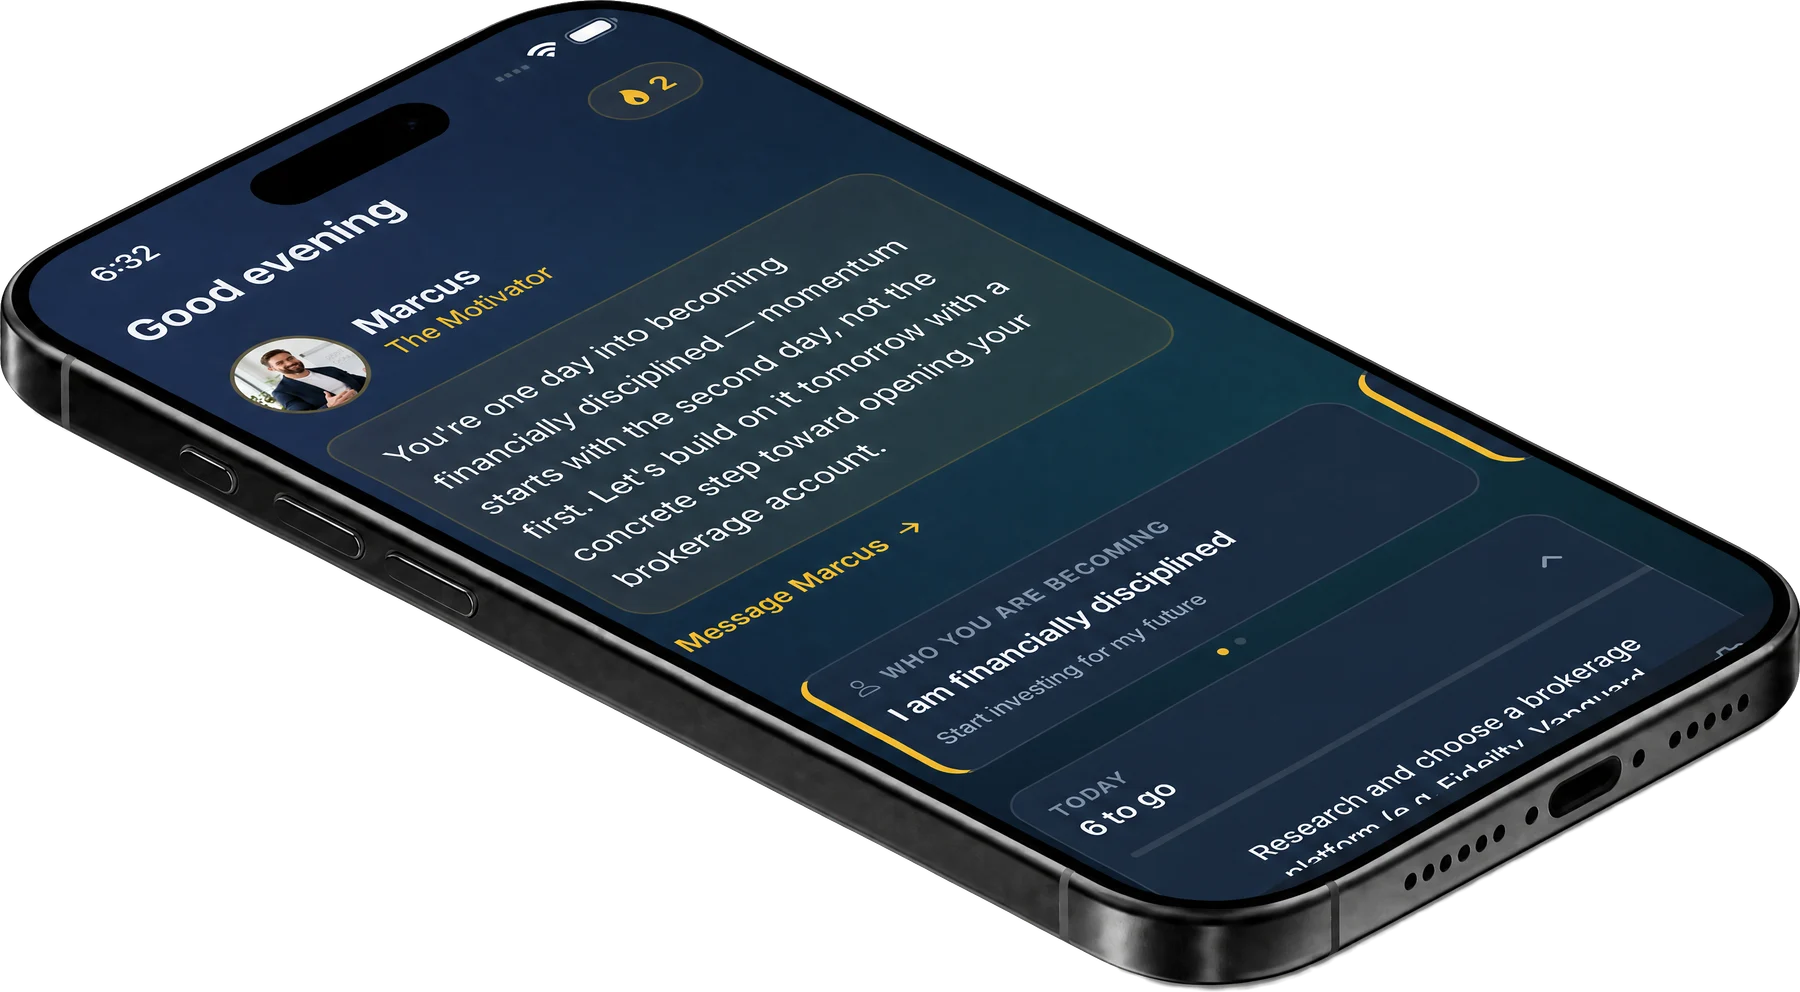
- Purpose-built coaching systems: structured around named frameworks, holding goals as records, running a defined process. This is the design class the trials tested and the class the evidence describes. It is also, for what it is worth, the class Odyssey is built in: GROW, OSCAR and Appreciative Inquiry as the running frameworks, goals and commitments held as structured records.
- General assistants with a coaching prompt: genuinely useful for thinking something through, and not what any trial tested.
None of which makes the trial results a claim about Odyssey. They are not; no published trial has tested it, and the samples below limit how far anyone should generalize. What the research does give a buyer is a design principle with evidence behind it: structure and follow-through are the active ingredients, so buy the product built around them, and the twelve questions will find it.
The limits, stated once
Three, and they are the ordinary limits of a young field rather than cracks in the result.
- The samples lean young. The PLOS ONE trials drew on undergraduate students, which the authors name themselves. Direction of effect is unlikely to reverse in working adults, but effect sizes should be held as estimates.
- It is mostly one research group. Replication by other groups is the next thing this field owes everyone. What exists so far is internally consistent across multiple trials and years.
- Goal attainment was self-reported. Standard in coaching research, worth knowing, and partly offset by the randomised control design: both groups self-reported, and the gap between them is the finding.
How to use this evidence when buying
Four questions, each one anchored to a finding above.
- Is it built for goals, with a named framework? That is the tested design class. A product that cannot name its framework is the untested one.
- Does it initiate, on a schedule? Frequency of use predicted the effect, so the feature that keeps you engaged in month four is the feature the evidence cares about. The demo is not.
- Is it selling goal progress or general wellbeing? The first is what trials found. The second is what they did not.
- Does it name its research honestly? Including what did not move. A company quoting only the 55 percent is selling; a company explaining the whole result is the one taking the evidence seriously. This page is our attempt at the second.
The evidence, in five lines
- Goal attainment rose 55 percent against 24 in a randomised six-month trial
- A chatbot coach matched human coaches on goal attainment over ten months
- The effect held three months after use stopped, and scaled with use
- Wellbeing measures did not move: the tool works on what it is pointed at
- What got tested was purpose-built, framework-driven coaching, not a prompt
Common questions
Is there evidence AI coaching beats a human coach?
No, and nobody serious claims it. What the trials found is that the chatbot matched human coaches on goal attainment, and given the difference in cost and availability, matching is the remarkable result. On the working relationship, humans stay ahead. The full comparison maps the two against each other.
Does the 55 percent figure mean I would improve 55 percent?
It is one group's average in one trial, so no individual promise follows from it, ours included. What it establishes is direction and size: structured AI coaching roughly doubled the control group's goal-attainment gain over six months, and the more people used it, the more they got.
Why did wellbeing not improve? Is that a failure?
It is a scoping result. The chatbot coached goals and goals moved; it did not coach wellbeing and wellbeing stayed put. The practical reading is that this category is a goal tool, should be bought as one, and should be sold as one, which is exactly where coaching ends and other professions begin.
Do these results apply to Odyssey?
Not as a claim, and we are careful about that: the trials tested other systems and no published trial has tested ours. What we can say is that Odyssey is built in the design class the trials validated, purpose-built goal coaching on named frameworks with scheduled follow-through, rather than the general-chat class nothing has tested.
Where should a skeptic start reading?
The PLOS ONE paper, "Comparing artificial intelligence and human coaching goal attainment efficacy", Terblanche and colleagues, 2022. It is open access, the methods are laid out plainly, and it is the single study that answers the most common objection, which is whether software can do the job at all.
The takeaway
The research says the category works at the job it is for. Goal attainment moved, substantially, in randomised trials; a chatbot matched human coaches on it over ten months; the effect grew with use and outlasted the trial. The boundaries are just as clear: the relationship advantage stays human, and nothing here supports wellbeing promises, from anyone.
Buy accordingly: a purpose-built goal coach, judged by whether you are still using it in month four, sold on progress rather than on feelings.
One thing to do today. Take the goal you would bring to a coach and write down what a 55 percent improvement in six months would concretely look like for it. That number is what the category is for, and it is the yardstick to hold any product against, ours included.